A Symfony app that tracks Amazon’s category tree on an hourly cadence
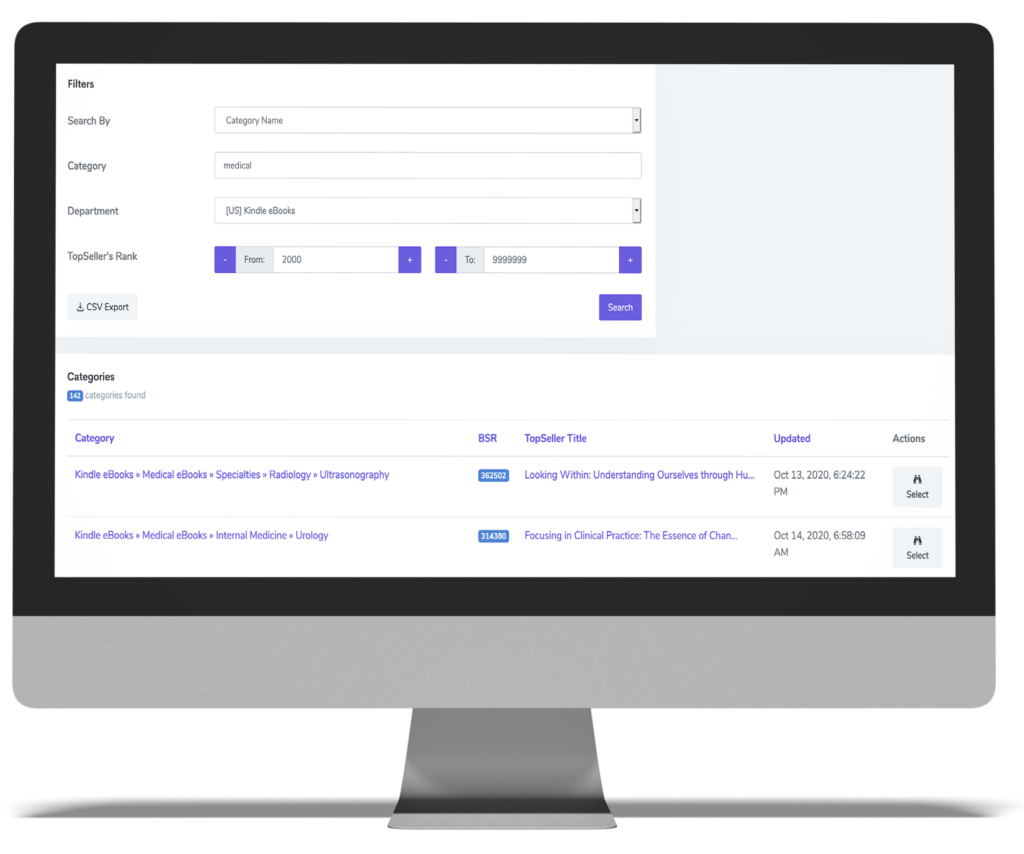
On Amazon, a book’s visibility depends as much on which categories it sits in as on how many copies it sells, and none of the data needed to make that choice well is available in one place. The official Product Advertising API gives canonical product metadata but not the live competitive picture inside a category, and the category tree itself runs to thousands of nodes that are reorganised, renamed and added to without notice. We built a Symfony application that closes that gap by running two data sources side by side: the official API for authoritative book data, and our own in-house scraper for everything the API doesn’t return.
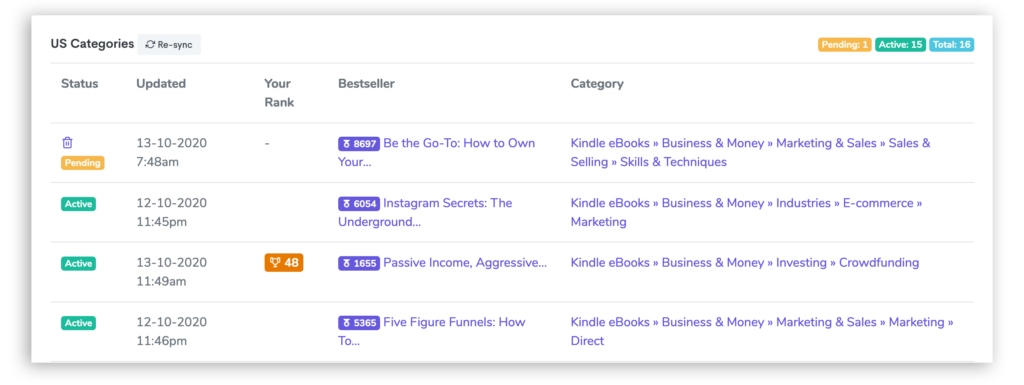
The scraper walks the full category hierarchy and the bestseller lists inside it, storing the tree rather than a flat list so that parent and child relationships, depth and node changes are all preserved between runs. Every pass is diffed against the last, which is what makes new, renamed and disappearing categories visible instead of silently corrupting the dataset. The same pipeline captures the top-selling titles in each tracked category and the author’s own book alongside them, so rank is always recorded in competitive context rather than as a bare number.
Running that hourly across every tracked book and category is the part that shapes the architecture. It is a scheduled, queued workload with retry and partial-failure handling rather than a single cron job: requests have to be paced, responses validated against markup that changes underneath you, and a failed fetch for one node must not take out the rest of the run. Rank and category data is stored as time series, so the history is queryable rather than overwritten, and it is that history the toolkit reads from when it ranks candidate categories by how competitive they actually are.
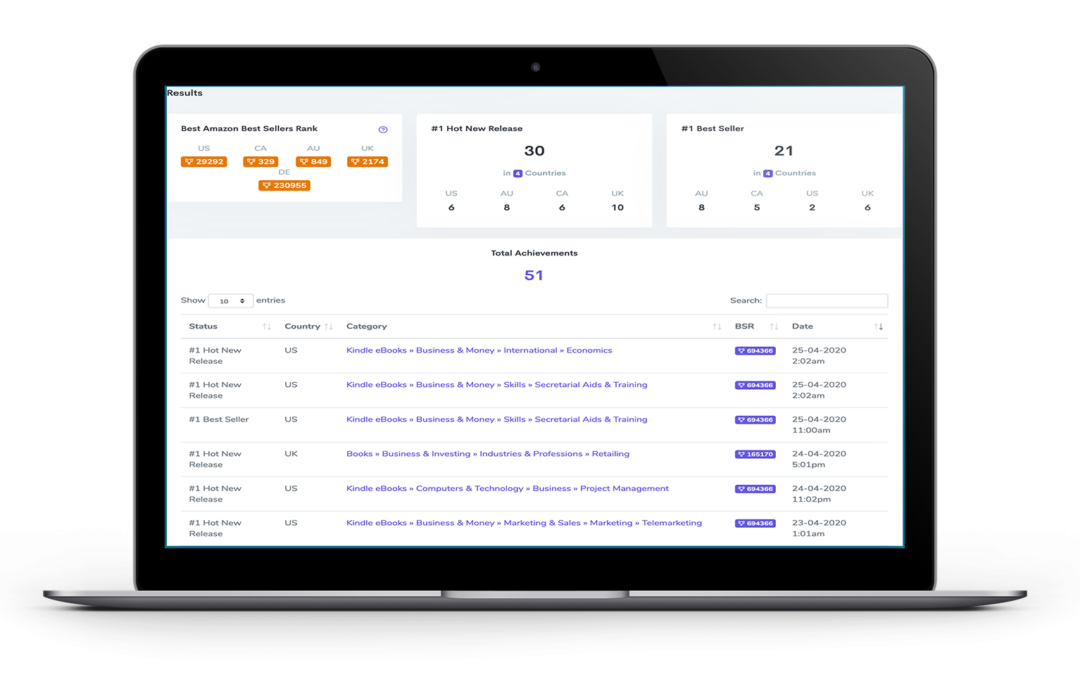
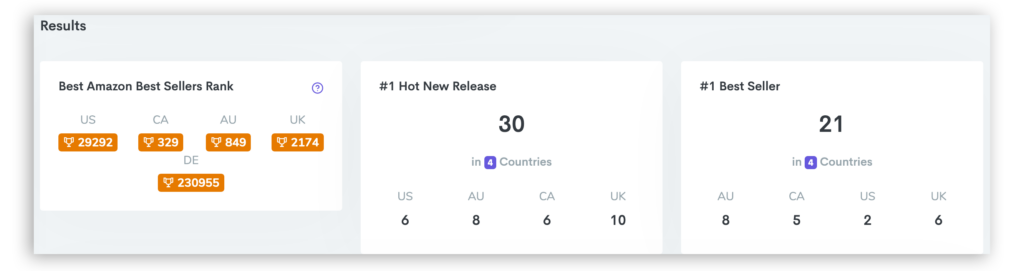
The system also watches for Best Seller and Hot New Release badges and renders hourly screenshots of every tracked category page and the book’s own listing. Badge detection is treated as a state transition, not a snapshot, so an achievement that appears at 2am and is gone by morning is still recorded, with a timestamped image to evidence it. For the author that means category decisions made on real data and a permanent archive of every ranking they have ever held, captured without anyone needing to be watching.